AI & Machine Learning 21h ago
· 12 min read
Your RAG Prompt Can't Fix Bad Retrieval
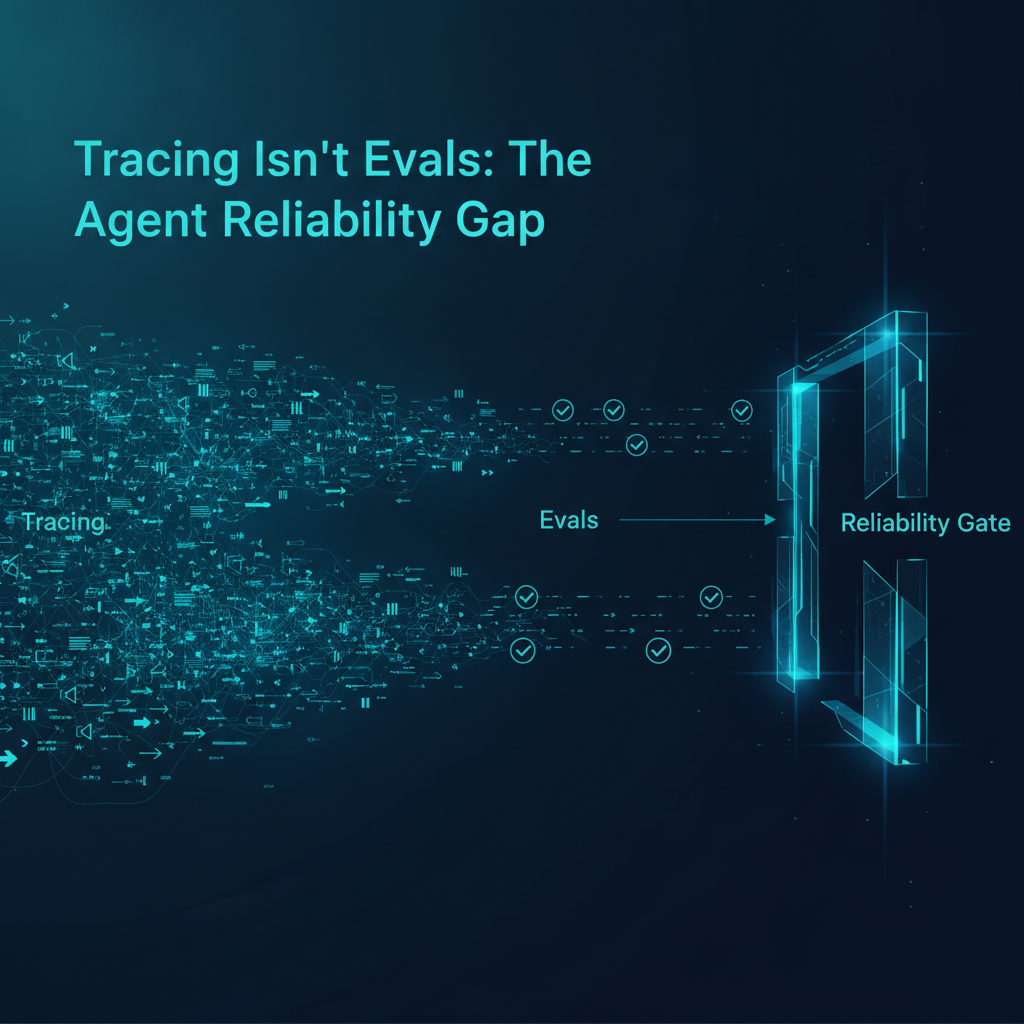
A new benchmark shows models follow individual RAG instructions 84% of the time but satisfy all of them in only 27% of responses. Here is the architecture that handles noisy, missing, and conflicting evidence outside the prompt.