 Bhanu Pratap
Context Rot Is a Memory Architecture Problem
Agents degrade well before their context window fills — a measurable failure mode called context rot. Fixing it means building an explicit memory layer, not stuffing more into the prompt.
Agents degrade well before their context window fills — a measurable failure mode called context rot. Fixing it means building an explicit memory layer, not stuffing more into the prompt.
A 1,600-trace failure taxonomy shows 79% of multi-agent failures come from specification and coordination problems at agent boundaries, not from any individual agent's reasoning — here's what that means for how you architect handoffs.
Time-to-first-token, not tokens-per-second, is what's quietly breaking under RAG and multi-agent workloads — here's why prefill and decode need separate infrastructure, and how to build for it.
IAM answers whether an agent can enter a system. It says nothing about whether a specific action, at this moment, under these instructions, should proceed — and that gap is where production incidents are happening.
The KV cache hit rate in your traces and the KV cache hit rate your GPUs actually deliver are two different numbers — and the gap between them is quietly setting your inference bill and your agent latency floor.
Anthropic's Fable 5.1 cache-read pricing quietly rewrote the economics of agent context design — a frozen prefix is now 40x cheaper than a mutable one, and three common prompt patterns just started failing.
Agent access models look fine at launch and then quietly widen with every new tool and workflow. Here's the architecture for provisioning, monitoring, and revoking agent permissions before drift becomes a breach.
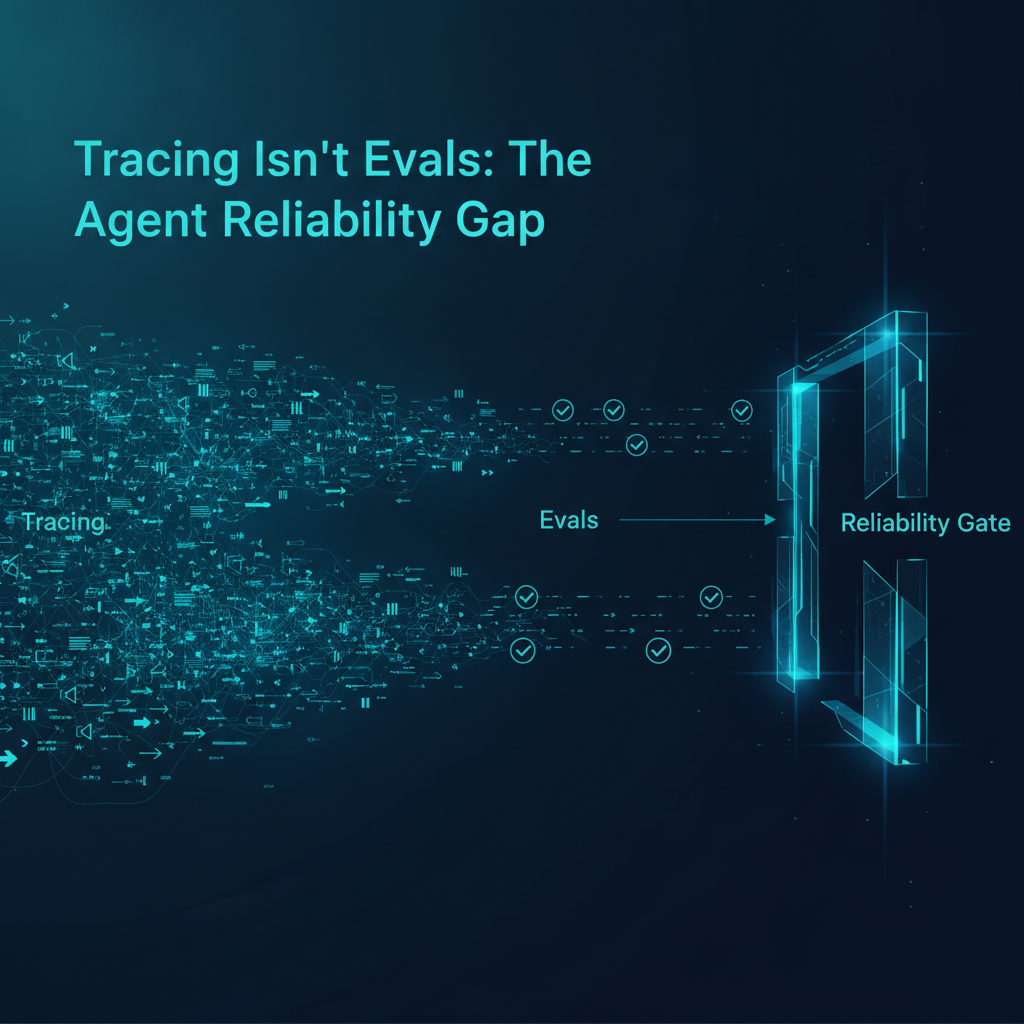
Most enterprise agent teams have full tracing but no evaluation loop — and that gap, not the model, is why production accuracy runs 20+ points below benchmark.
Headless Chromium is the default 'browser tool' for AI agents, and it's quietly becoming the most expensive, least reliable line item in agent infrastructure. Two hyperscaler moves this month show what replaces it.
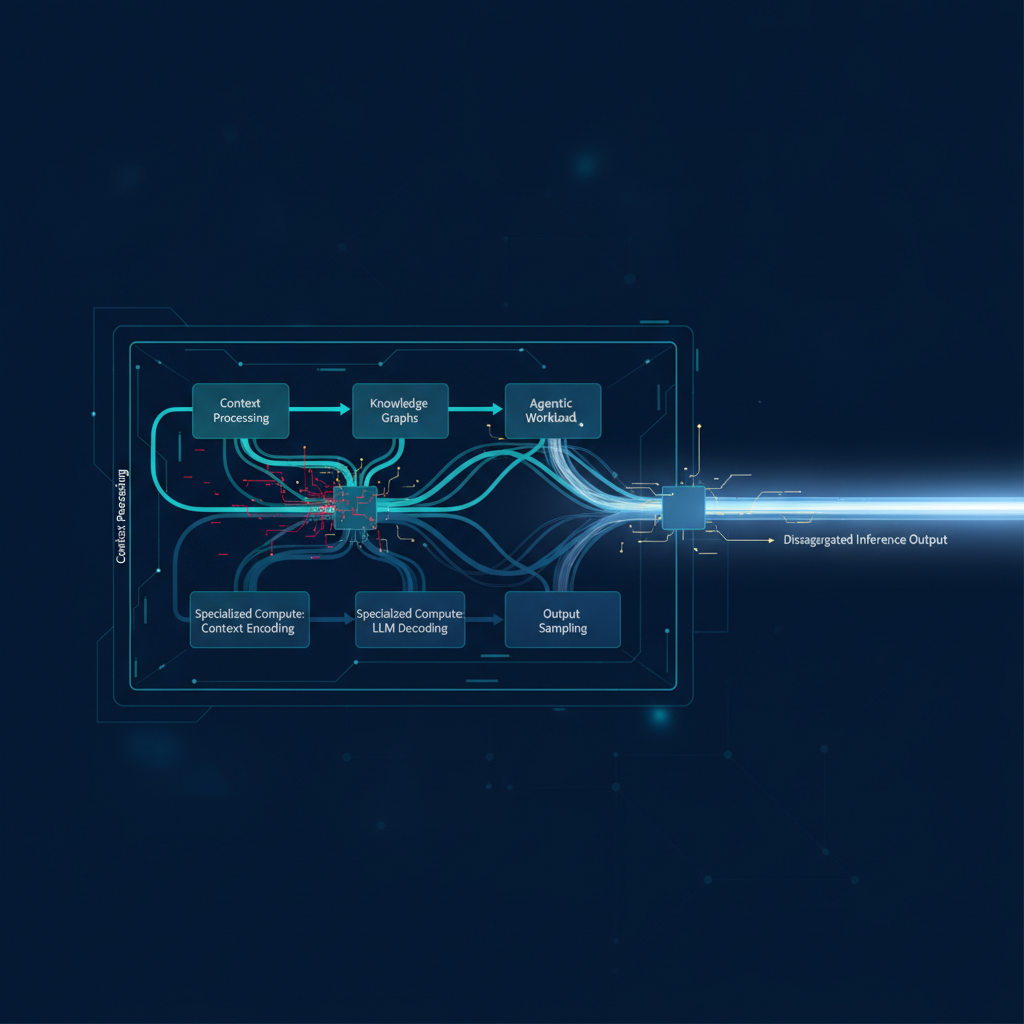
Agent loops are decode-bound, not prefill-bound, and most enterprise serving stacks are still sized for the wrong bottleneck. Here's what changes in your architecture and why disaggregated inference is becoming the default pattern, not a hardware shopping list.
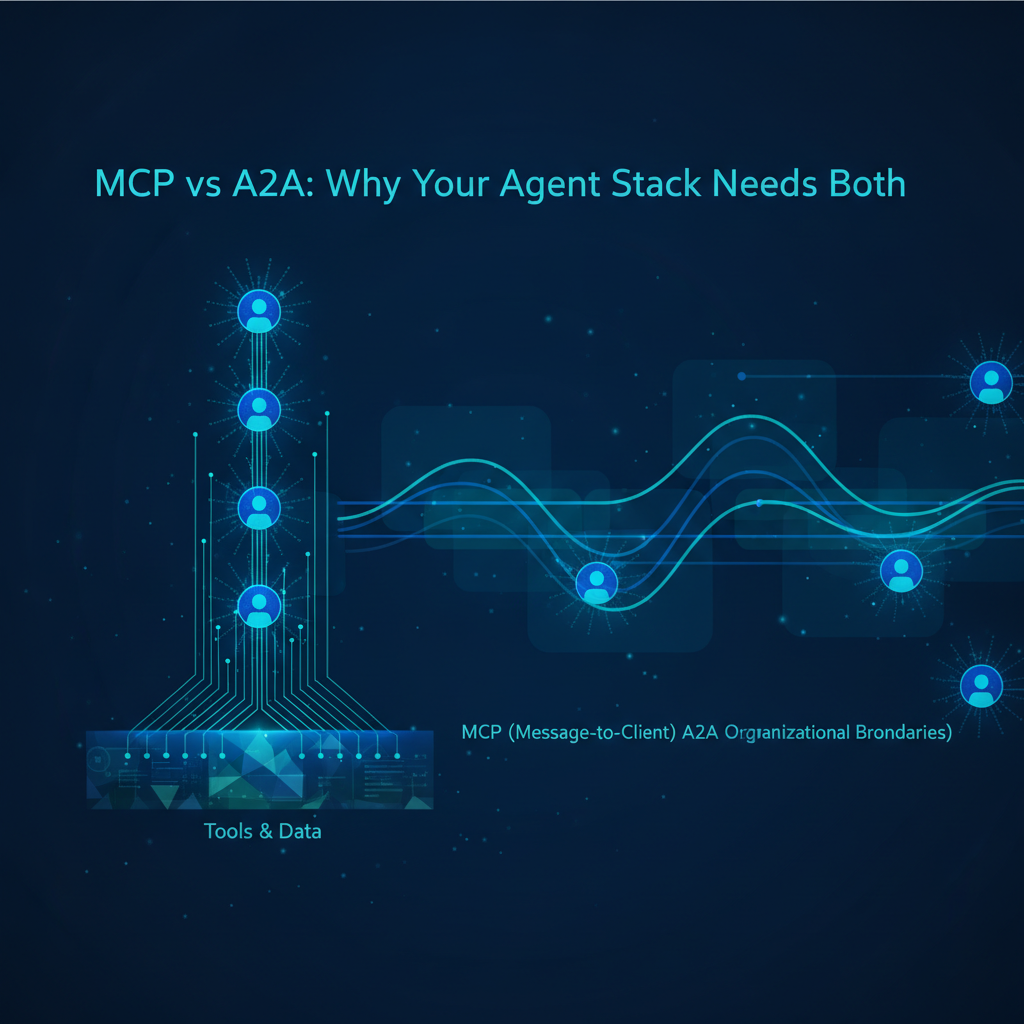
Teams keep trying to make one protocol do both jobs — tool access and agent-to-agent negotiation. Here's why that's the wrong architecture, and what to build instead.
94% of teams have agent observability in place, yet only 12% say they can actually govern their agents — the gap isn't a tooling problem, it's an unassigned architectural responsibility.
New evidence shows agentic keyword search hits 94.5% of RAG faithfulness with zero vector store — here's how to decide whether your team still needs one.
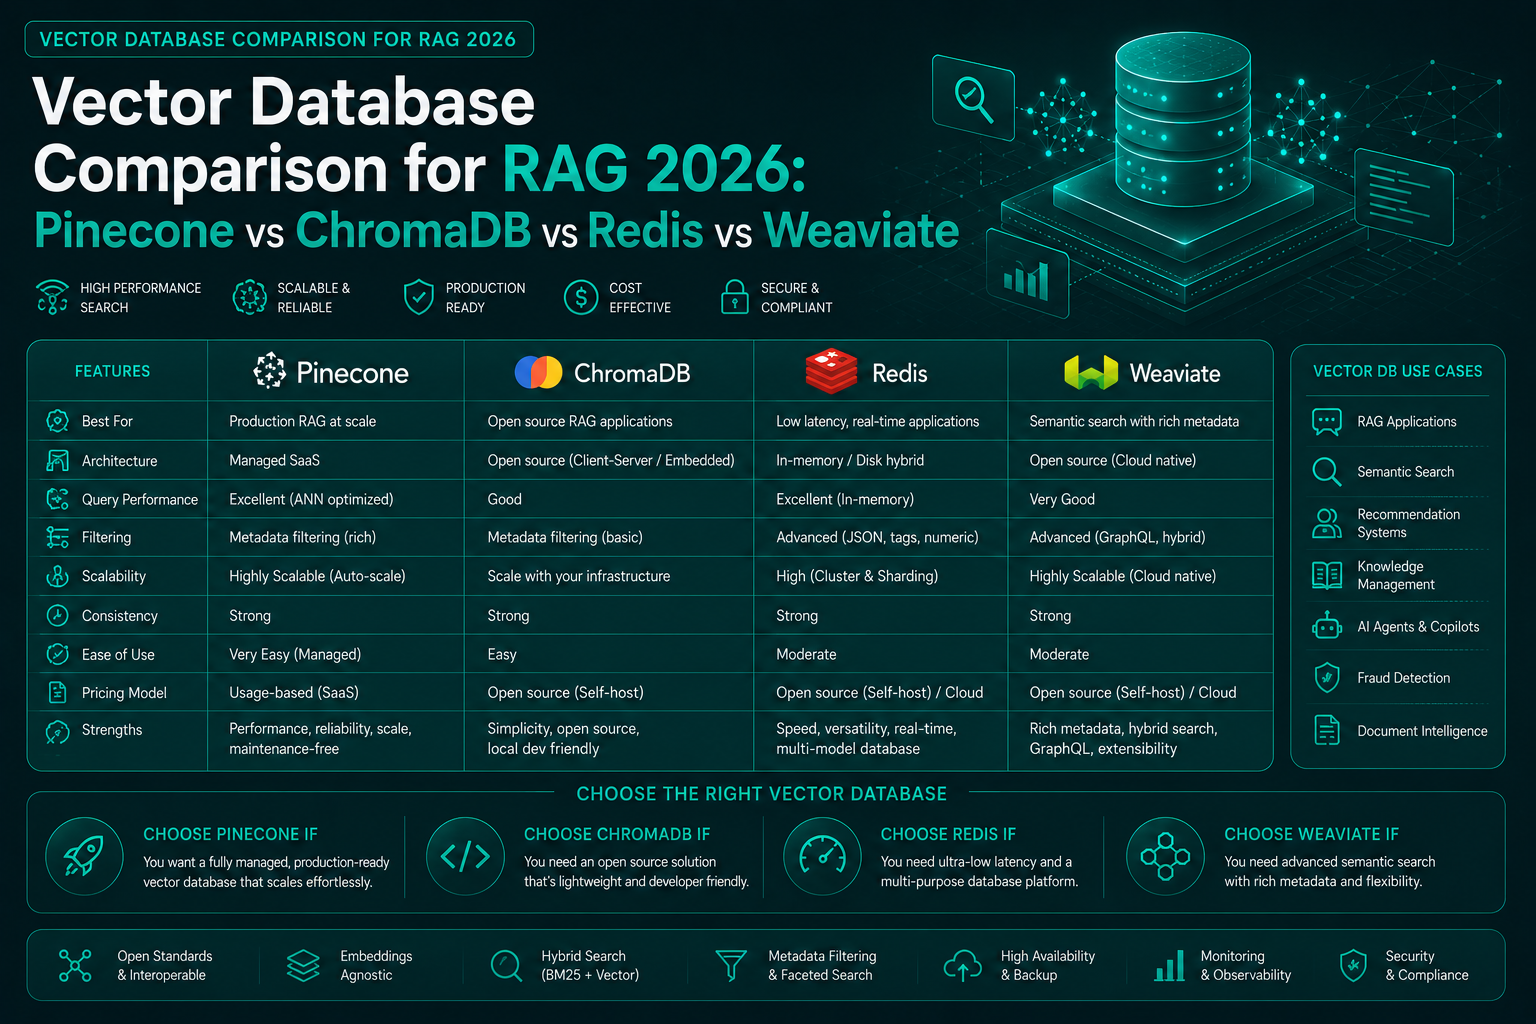
The vector database you choose for your RAG system determines more than retrieval speed — it shapes your architecture's scalability ceiling, operational complexity, cost model, and what filtering capabilities you have at query time. This is the production comparison for teams choosing in 2026.
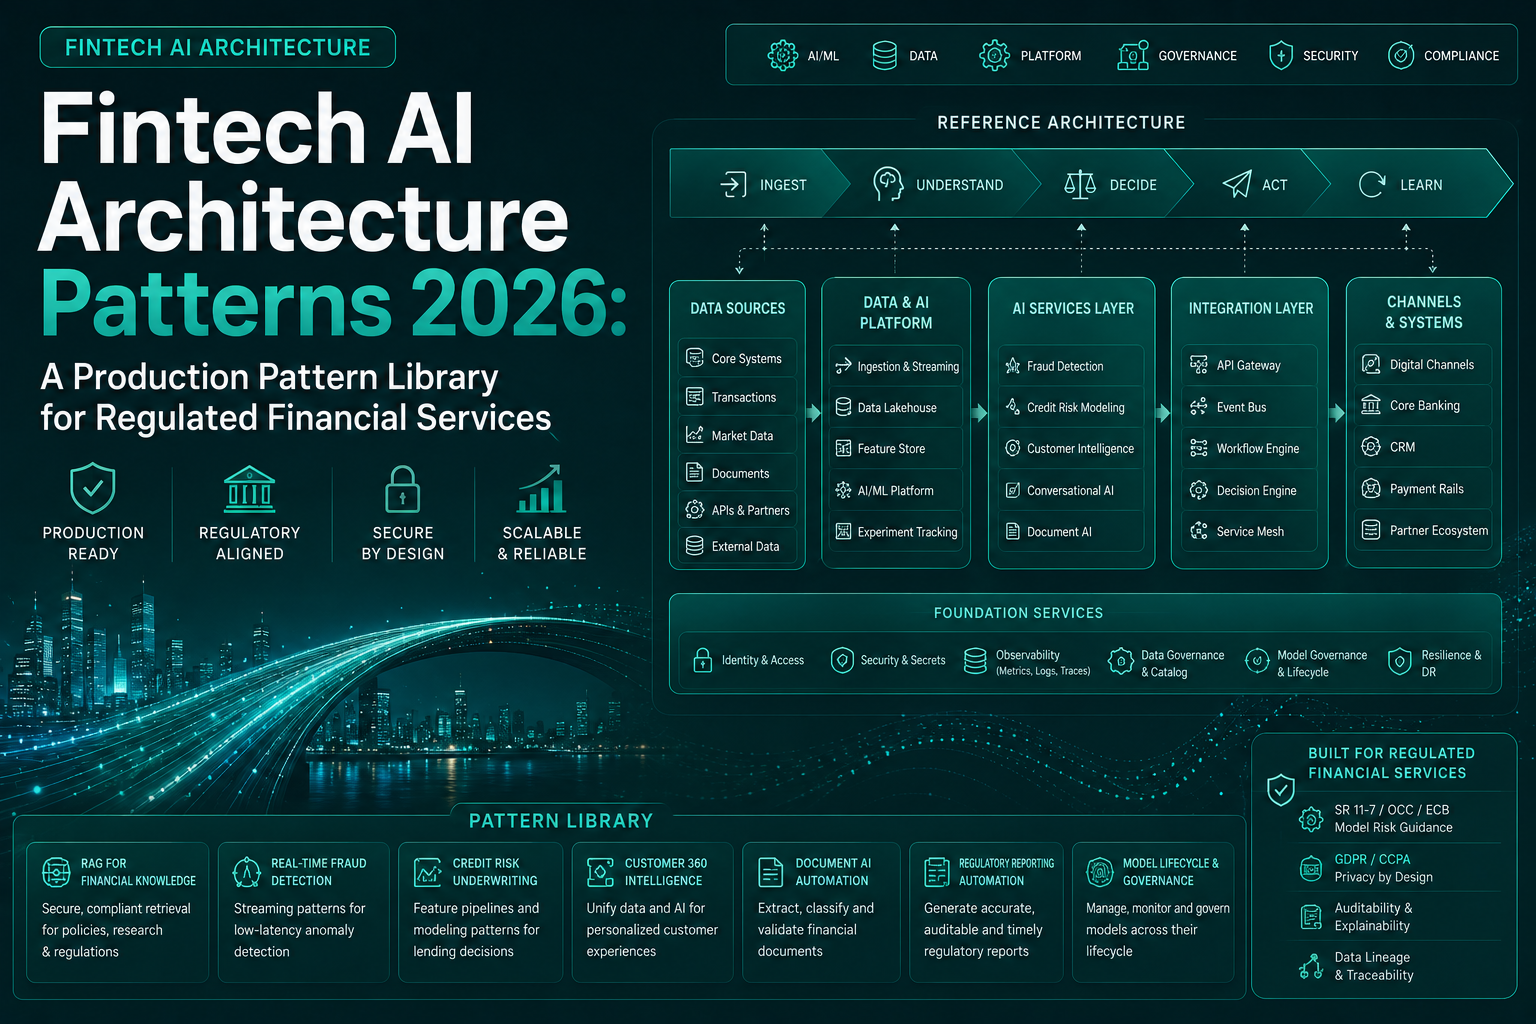
Most AI architecture guides are written for startups deploying on greenfield infrastructure. Financial services has different constraints: regulatory audit requirements, latency SLAs on core banking integrations, data residency rules, fair lending exposure, and model risk governance. This is the pattern library for AI architects building production systems inside those constraints.
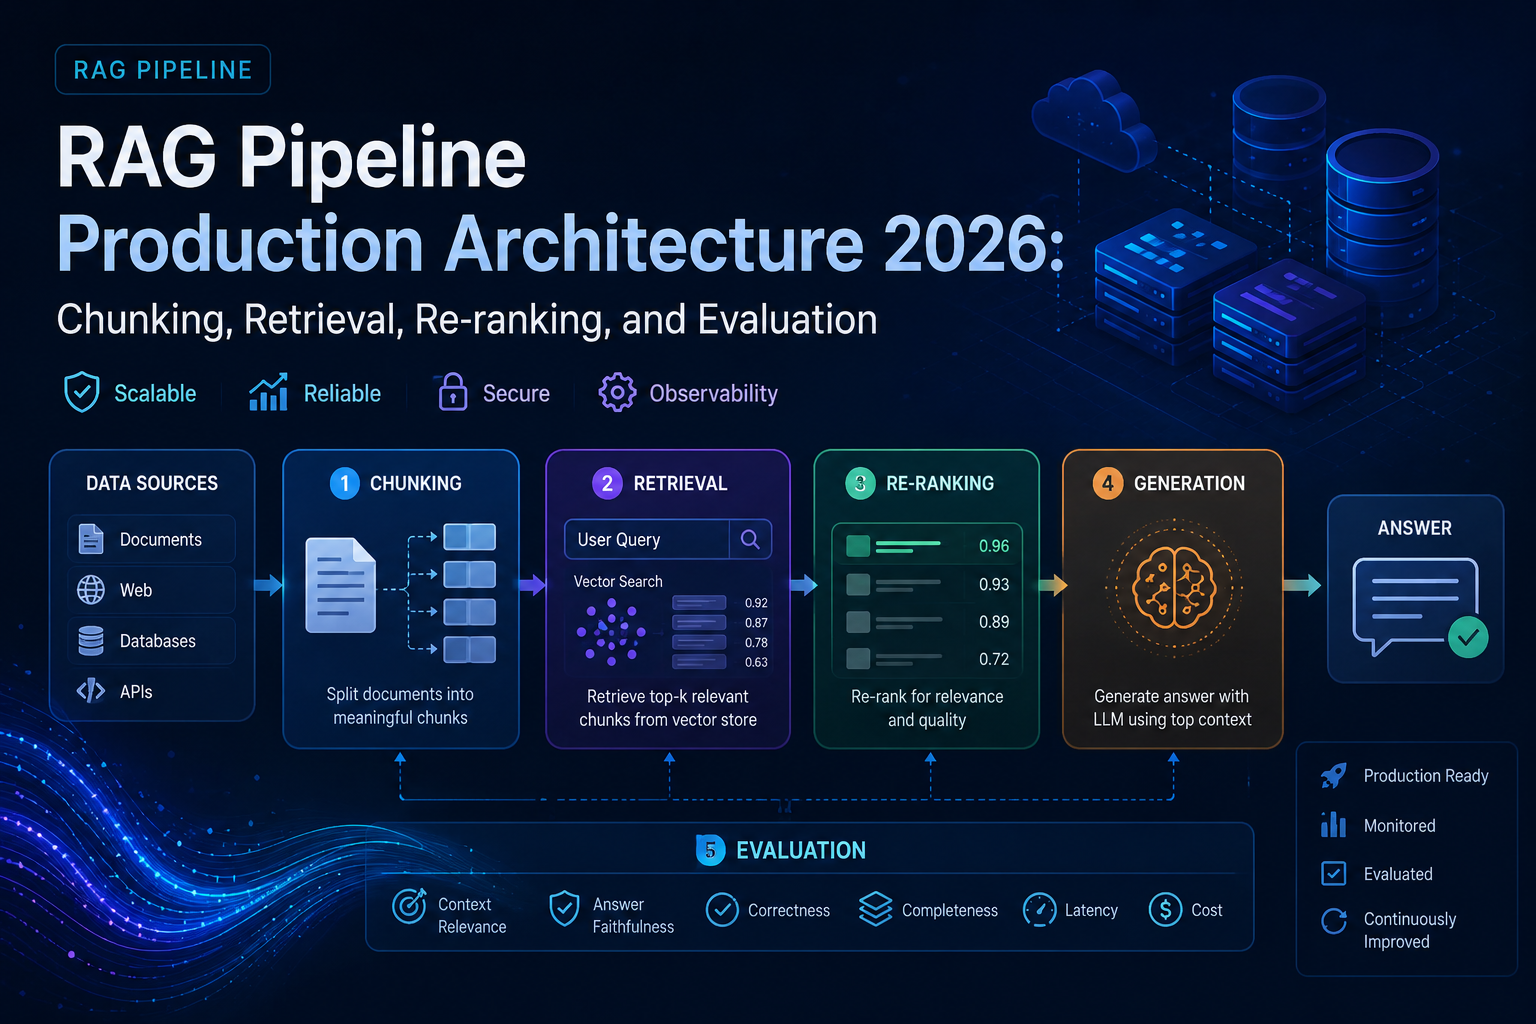
Most RAG tutorials get you from zero to a working demo in 30 minutes. Production RAG takes 6–12 months to get right, and the problems that sink it are not the ones covered in the tutorial. This is the production engineering guide: chunking strategy, hybrid retrieval, re-ranking, evaluation frameworks, and the operational patterns that keep RAG systems working after launch.
Google I/O 2026 shipped a complete agent stack — Gemini 3.5 Flash, Managed Agents API, Antigravity 2.0, and Agent Identity. The ephemeral-by-default execution architecture is elegant engineering and a potential compliance trap for any regulated industry running AI at decision-level stakes.
A May 2026 OX Security disclosure revealed a systemic vulnerability across MCP SDKs with 150M+ downloads — and the real problem isn't the CVE, it's that most enterprise agent deployments have no controls in place to stop what comes next.
OpenAI's new Guaranteed Capacity offering looks like a cloud pricing deal. It's actually a multi-year architectural commitment that changes how teams design for reliability, route across models, and govern production AI — and most enterprise teams aren't modeling the risks before they sign.
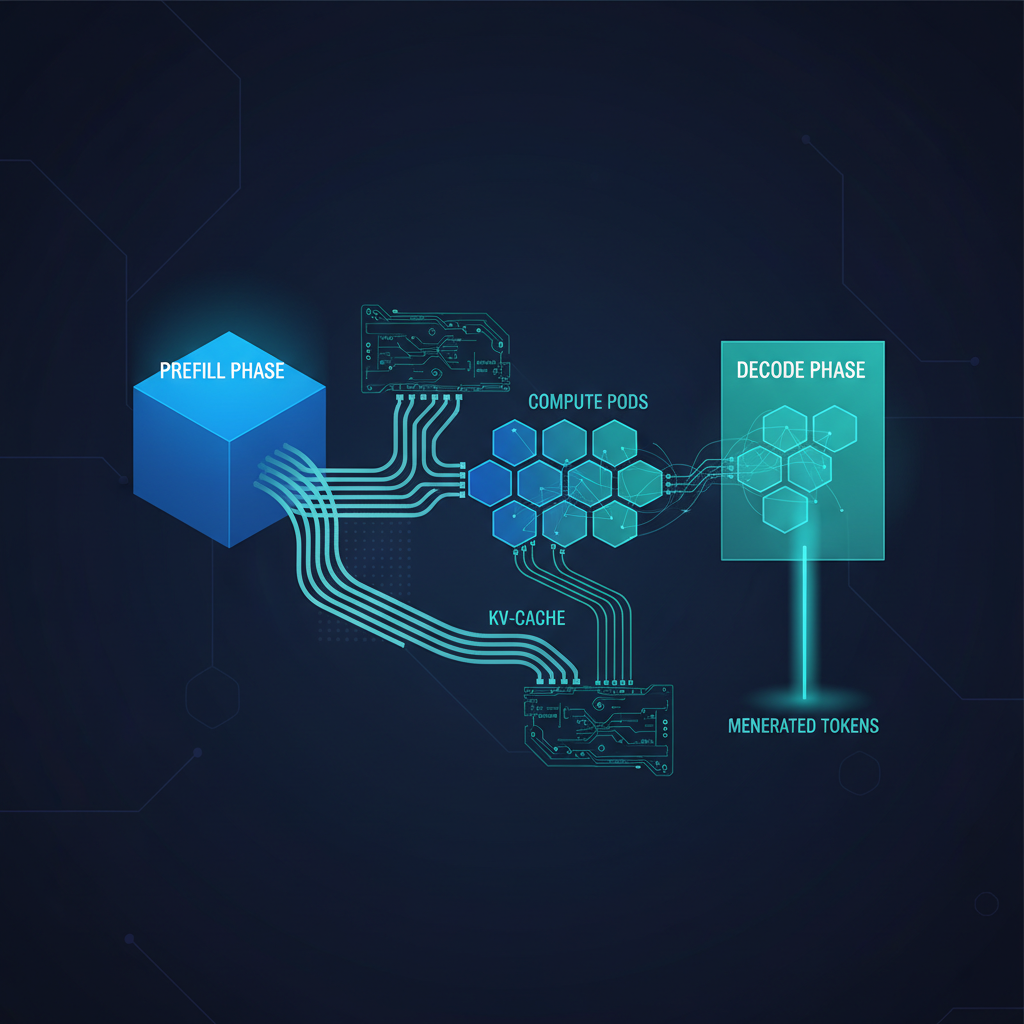
llm-d v0.7 ships predicted-latency scheduling to GA and joins the CNCF — forcing enterprise AI teams to confront the structural ceiling of monolithic inference and treat LLM serving as a real distributed systems problem.
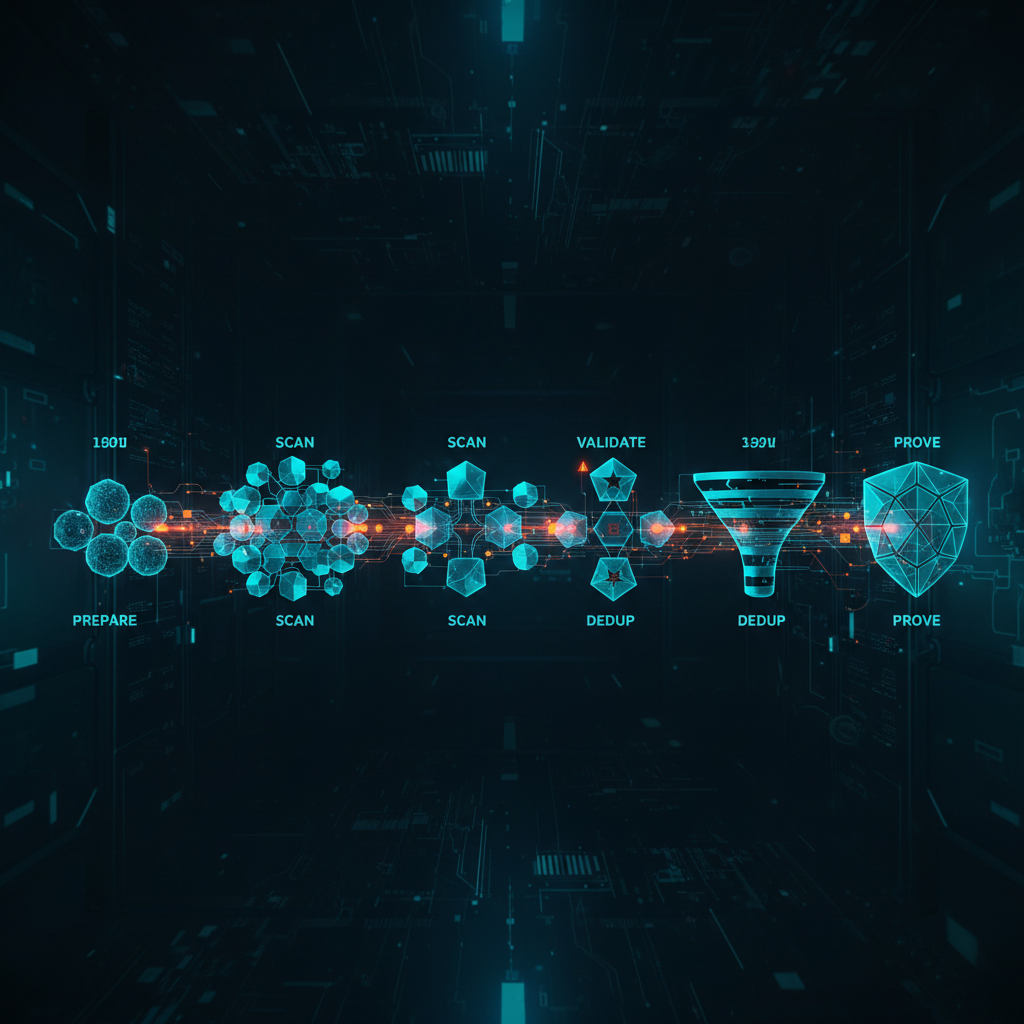
Microsoft's MDASH multi-model agentic scanning harness found 16 Windows vulnerabilities including 4 Critical RCEs — not because of any single model, but because of a 5-stage pipeline of 100+ specialized agents. The architecture lesson rewrites how enterprise teams should think about agentic AI for production security work.
OpenAI's Deployment Company and Tomoro acquisition show why enterprise AI fails after the demo: integration, governance, data access, observability, and FDE handoff risk.
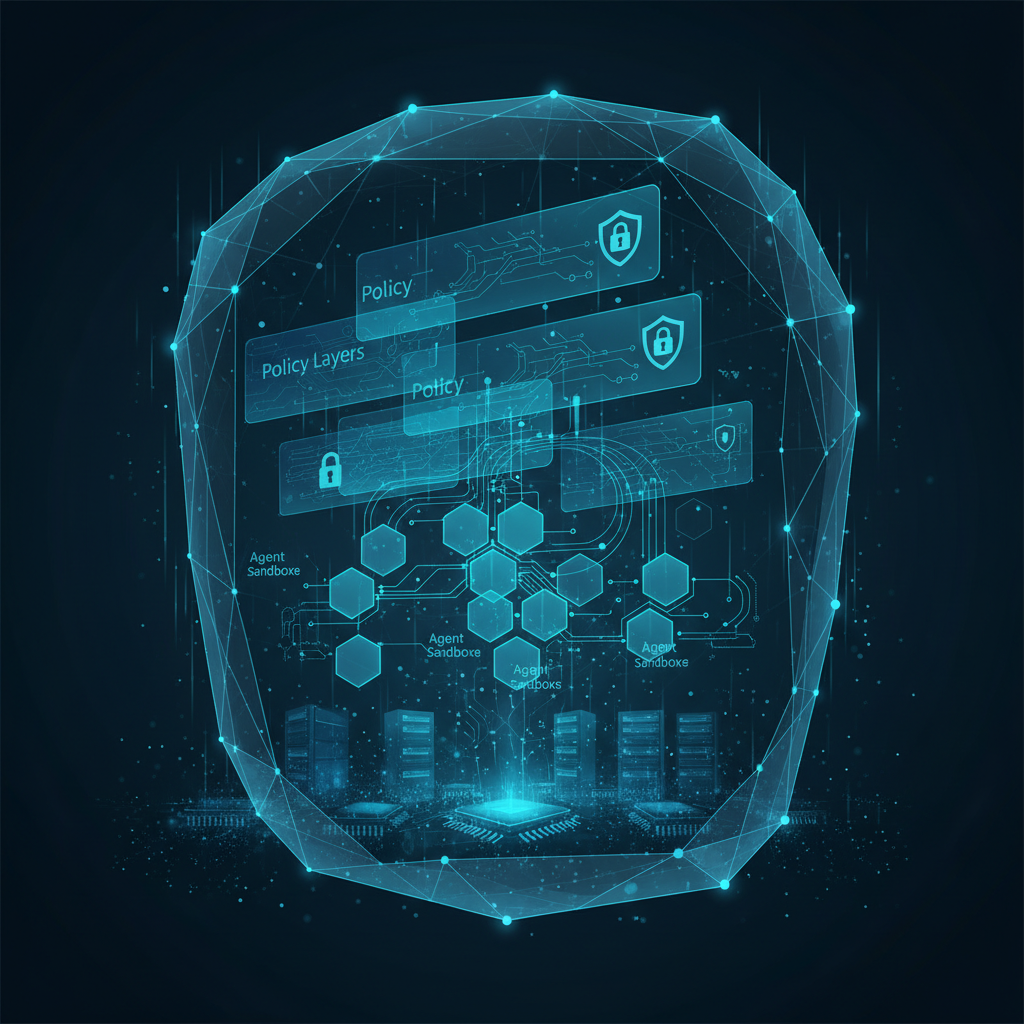
SAP Sapphire and Red Hat Summit both landed this week with NVIDIA OpenShell at the center of their agent architectures. When the same runtime sandbox shows up in 17 enterprise stacks simultaneously, that's not adoption — it's standardization, and it reshapes how you design production agent systems.
Atlassian's new MCP tools cut token costs by 48% — which tells you everything about how badly MCP context bloat was burning enterprise budgets. Combined with ServiceNow and SAP metering agent data access, the real cost of cross-domain agent orchestration just got a price tag.
F5's 2026 State of Application Strategy Report drops a number that should alarm every platform architect: the average enterprise is now running seven AI models simultaneously in production. The traffic cop that routes between them, governs them, and keeps them from burning your budget? Most enterprises don't have one.
When the two largest model labs simultaneously launched forward-deployed engineering ventures backed by Wall Street capital, they didn't just change how AI gets sold — they changed who owns your production AI architecture. Here's what that means for engineering teams trying to stay in control.
When Microsoft, AWS, Google, ServiceNow, and Okta all ship 'agent registries' within weeks of each other, enterprise architects need to read that convergence carefully — because the agent inventory problem is now a compliance deadline, not a backlog item.
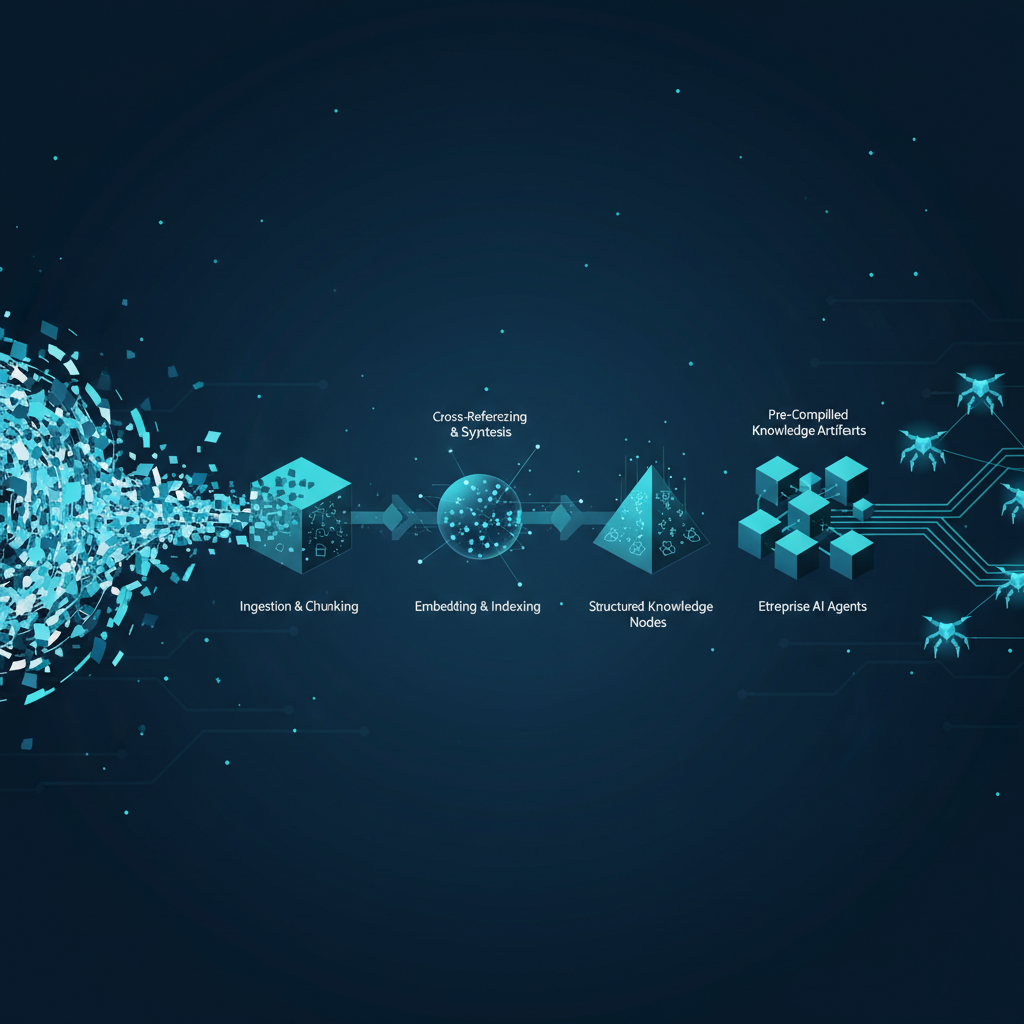
Pinecone's pivot from vector database to 'knowledge engine' exposes a structural flaw in how enterprise teams built their RAG stacks — and signals a new architecture layer between raw data and agent runtime that will reshape how production AI systems are designed.
Cerebras's S-1 lands with a 750 MW OpenAI inference contract, an $1B circular loan, and 86% revenue concentration in two customers — and quietly forces enterprise AI teams to make a routing decision they've been postponing.
Google just retired the Vertex AI brand and replaced it with the Gemini Enterprise Agent Platform — a unified build-scale-govern-optimize stack for autonomous agents, backed by 200+ models and two brand-new TPU generations. Here's what it means for practitioners.